Essays#
This is the place within Notes for reflections, opinions, observations, retrospectives, and direction-setting posts.
- Commentary on events and things I notice
- Notes on direction (blog, work, life)
- From short reflections to longer essays
Latest Posts
I Was Collecting Token-Saving Tips, Then I Opened My Logs and Changed the Order
While researching tips for cutting token usage in Claude Code and Codex, I aggregated my own session logs. Most of my usage came from a handful of very long sessions, and some popular tips did little for my usage pattern. This essay covers the order of changes I settled on and a simulation of auto-compaction thresholds.
I Knew the Harness but Not What Was Inside — Learning How Coding Agents Are Built and How They Run Through OpenCode 2 and Hermes
While writing up OpenCode 2.0, I wanted to compare it with Hermes Agent, which I use every day. But I only knew the concept of a harness and the features of coding agents; I had never actually looked at how they are put together or how they run. So I read the source code of both open source agents, first learned the basic parts of a coding agent and the path a single request takes, and then used that map to read OpenCode 2 and Hermes one by one before comparing them. This is the record of that learning.
Taking the Design Instead of Buying the Reviewer — Claude Code Review and the PR Agent I Built Myself
After Anthropic made Claude Code Review generally available and GitHub shipped AI Scan, agentic autofix, and Actions workflow lockfiles, I looked at whether to adopt them. I already run a PR agent I built myself that handles everything from review to merging, conflict resolution, and deployment, so instead of bringing in the products, I picked which parts of their design to borrow and which to leave behind, and drew up an improvement plan for my own agent.
Why Is No One Building the Dream Coding Agent?
Michael Lynch's 'Why are coding agents so dumb?' lists 17 conditions for a dream agent. This essay checks them against the October 2026 state of Claude Code, Codex, GitHub Copilot, and Cursor, and of open-source agents such as Hermes Agent, OpenCode, and Pi. It sorts the remaining gaps into three kinds: defaults that clash with serving everyone, features that clash with model vendors' interests, and technical problems no one has solved yet. Then it asks whether a new coding agent aimed at a specific group of users has room to win.
What Is 72.4% a Score Of? — How to Read LLM Benchmarks
This essay starts from a discovery: the 72.4% OSWorld score for Claude Haiku 5.5 that I copied into an AI news brief was a partial-credit score, not a completion rate. From there it covers what a benchmark is made of (tasks, grading, and run conditions), the concept behind SWE-bench and the lineage that grew out of it, saturation and contamination, the major benchmarks seen most often today, grader defects, and the incentives in the benchmark ecosystem. Because a benchmark number is a score for a set of conditions rather than for a model alone, the conclusion is to use public benchmarks to shortlist candidates and your own evaluation to make the final call, with a checklist for reading benchmark numbers.
The Sandbox I Turned Off Because It Got in the Way — Rethinking Agent Isolation Before Turning It Back On
I had turned off Claude Code's sandbox for the sake of speed and managed the risk by reading the agent's responses carefully. The general availability of Microsoft MXC prompted me to re-examine the assumptions behind that decision. This essay covers why reading responses is only an after-the-fact review, why agents need isolation through the lens of the lethal trifecta, the dimensions and strength levels of isolation, and why fake environments are rare. It then walks through the friction I can expect when turning the sandbox back on and how configuration can reduce it, based on the official documentation.
Will the Day Come When My Users' Subscriptions Pay for My App's AI? — Sign in with ChatGPT and MCP Events
For third-party app developers, API pricing is far more expensive than an AI subscription. Sign in with ChatGPT, announced at OpenAI DevDay 2026, is the first official path that lets an outside app charge its AI usage to the user's ChatGPT plan. This essay measures how far that door is actually open, which apps and which users can pass through it, and where Anthropic, Google, and GitHub stand on the same question. It also explains how MCP Events, announced the same day, connects to this trend and suggests what you could build with it.
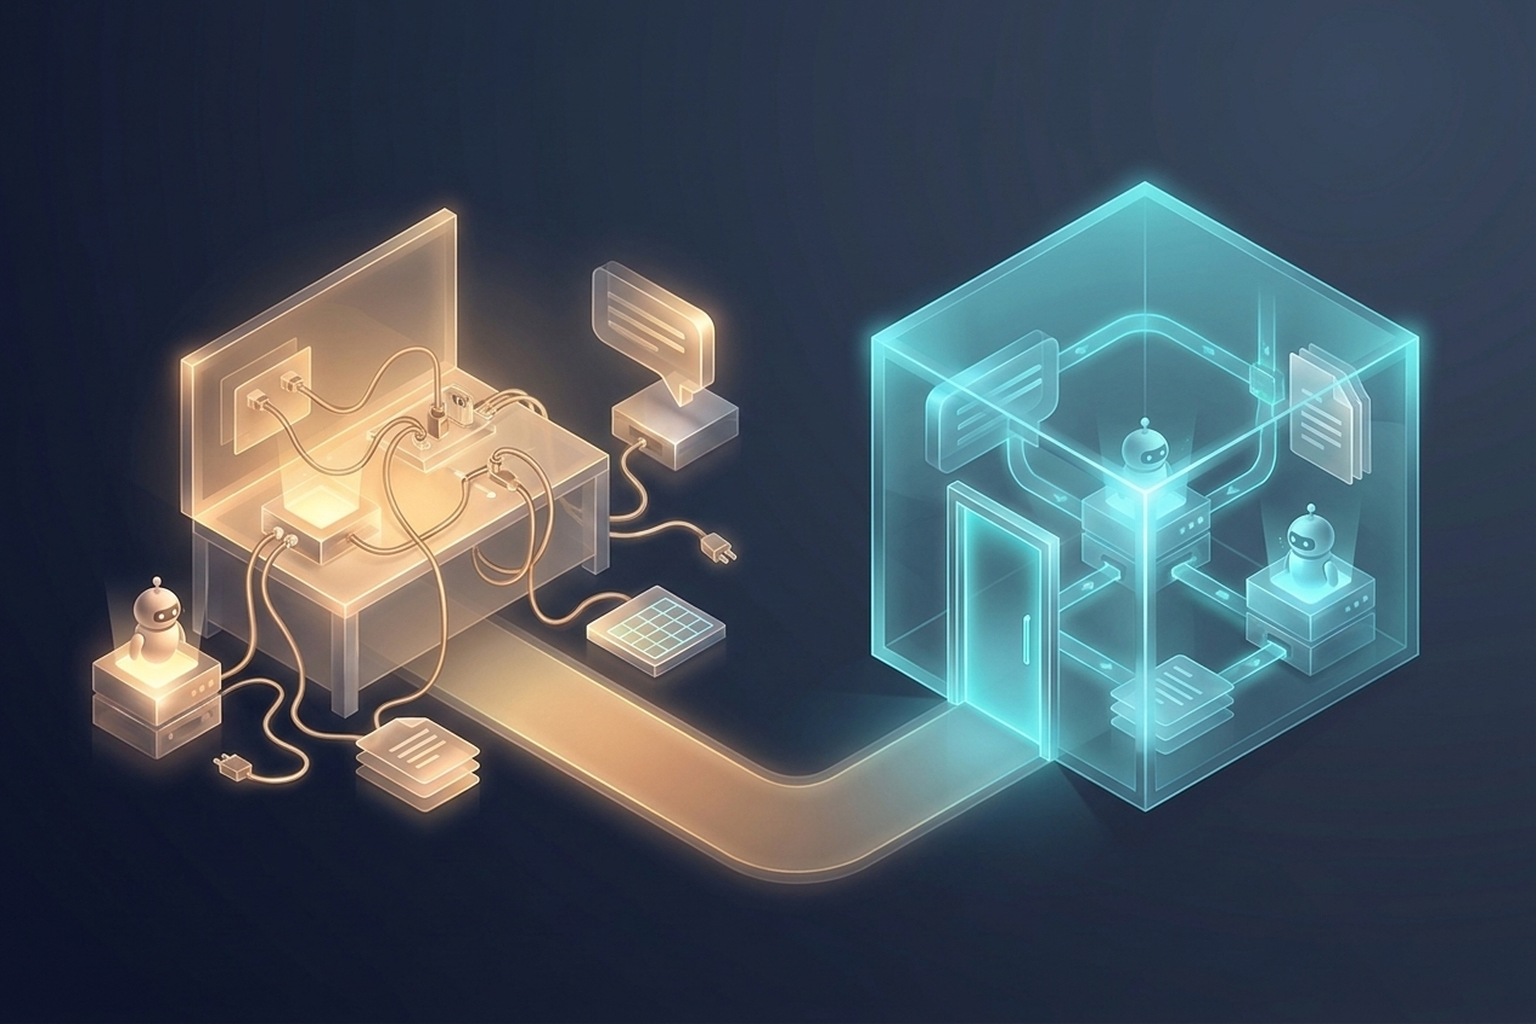
A Hand-Assembled Agent Stack vs. OpenAI's Finished Product — Looking at dots and ChatGPT Space
A look at the main features of dots, OpenAI's always-on agents, and ChatGPT Space, its shared team workspace, both announced at DevDay 2026, compared with the agent environment I assembled at work from Hermes, Slack, Notion, and Google Sheets. The essay weighs the upside of building a similar environment easily inside the OpenAI ecosystem against the downside of being locked into it, and suggests projects worth trying with dots and Space.
Rules from Memory to Code — Can Claude Code Mods Enforce My Blog's Writing Rules?
A look at Mods, the new extension mechanism Anthropic added to Claude Code, and a comparison of three ways to handle a writing rule that lives only in a Markdown file: leaving it to the model's memory, blocking it with a settings hook, and enforcing it with a mod. The difference is small for a one-line ban but grows for rules that span a whole turn or need a human decision. The essay also explains why mod interfaces don't appear in the Cursor extension and proposes mods worth building for this blog.
Older Posts
2026
- Why an AI Subscription Isn't a Cheap API
- I Dug Into Prompt Caching and Found That Hit Rate Isn't the Goal
- The Two Walls You Hit When You Hand an Agent a Browser
- Context Switching in the Age of AI Agents — When You Become the Scheduler
- Hunting Down an Active-User Crash — Bots, Illusions, and an Indexing Collapse
- Why Do Coding Agents All Design Alike? — Research and Decisions Behind Choosing a Design Stack
- LLM Wiki, Opened Up — The 'Automatic Memory' Myth and a Schema That's Just a Few Lines
- What Do Feature Flags Actually Solve? Single-Branch Collaboration and the Myth of Google-Style Trunk Development
- I Thought AWS Bedrock Was Just Relaying Models — Turns Out It Runs Them Directly
- An AI Tools Knowledge Map — Lining Up the Materials for Process-Improvement Consulting
- I Decided to Call Them Harness Skills — Breaking the Illusion of Doing Well and Opening Up My Harness
- An Agent That Keeps Working After the Laptop Closes: Remote Development with Lightsail, Hermes, and Discord
- How Product Development Processes Should Change in the Age of AI Agents
- Hermes Agent — Is It the Luxury Brand of AI Agents? A First Impression
- How to Add Coding Runtimes to an AI Agent Web Service
- Claude Managed Agents — Can It Replace Your Existing Agent System?
- In the AI Era, How Will Work Be Divided Again?
- Where Should You Use Codex? A Guide to CLI, App, Cursor, and Claude Code
- Harness Engineering — A Practical Guide to Safe AI Agent Operations
- In the AI Era, What Should Developers Own?
- Installing and Analyzing OpenClaw: A New Standard for Personal AI Agents
- First Impressions of Claude Cowork: Bringing Agents to Non-Dev Work
- Revisiting Ted Factory’s Direction in the Agent Era
- Finally Finding My Blog’s Direction: Turning It into a Content Factory